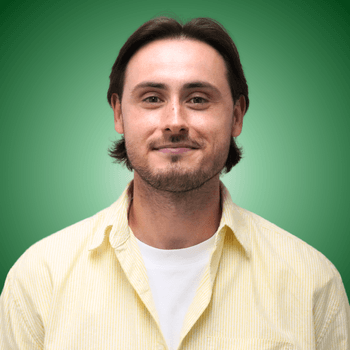
Sam Warwick


Sam is a Senior Consultant operating within the North American market, while maintaining strong ties to his European network. He specialises in placing professionals at the intersection of machine learning and AI infra. His domain covers Data Science & Machine Learning, Infrastructure & Engineering, and Product.

With over six years’ experience in recruitment, Sam has a proven track record of identifying the right individuals to meet strategic goals, drive innovation, and add a fresh dynamic to established teams, all while respecting the parameters of each professional relationship. He works by the principle: we have two ears and one mouth for a reason; listening twice as much as we speak leads to better outcomes.

Fuelled by a lifelong devotion to football (yes, he supports Tottenham - please send thoughts and prayers) and a not-so-guilty obsession with Star Wars, Sam splits his time between the pitch and a galaxy far, far away (when he’s not immersed in the field of Geo, of course). Lest we forget, he’s powered by long runs and low heart rates; catch him in Zone 2, where the pace is chill, but the gains are real.

At DeepRec.ai, we’re more than recruiters; we’re strategic partners. As a certified B Corp, we’re committed to making a positive impact on people and the planet, with diversity and inclusion woven into every stage of the hiring journey. Whether you're advancing AI or seeking specialist talent, Sam is here to support your mission.

Connect with Sam to explore how he can help bring your deep tech vision to life.
Jobs from Sam Warwick

Miami, United States
Research Engineer (Inference)
Research Scientist / Engineer, Inference San Francisco | Permanent DeepRec has partnered with a frontier AI research lab that designs its own model architectures from the ground up. Serving cost is treated as a research question here, so inference sits at the centre of the work rather than the end of it. The Opportunity You'll own latency and throughput across two serving stacks. One handles production traffic for customers. The other powers test-time compute and RL rollouts for the research team, so every gain you make speeds up the research itself.   What You'll Do Cut latency and raise throughput for model serving at very high concurrency Speed up RL rollout generation and scale test-time compute for research Tune batching, caching, load balancing and parallelism across the serving stack Write and profile GPU kernels in CUDA and Triton Apply quantization, distillation, speculative decoding and low-precision numerics Shape model and hardware co-design with serving cost in view from day one Own benchmarking, testing and reliability for every inference service What You'll Bring Essential Production experience with vLLM, TensorRT-LLM or similar at high concurrency Hands-on continuous batching and KV cache management Quantization for inference in production Profiling and performance analysis with CUDA and Triton Desirable Speculative decoding or multi-node serving Performance tuning on H100 or B200 hardware Kubernetes and production infrastructure We encourage you to apply even if you don't meet every requirement. The right mindset matters as much as the right CV.     Apply Now If you've spent your career making models fast, this is a place where that work shapes the research agenda. Send your CV and we'll share the full brief in a confidential conversation
Sam WarwickSam Warwick
Miami, United States
Research Engineer (Pre-Training)
Research Scientist / Engineer, Pre-training San Francisco | Permanent DeepRec has partnered with a frontier AI research lab building new model architectures, not fine-tuning someone else's. Pre-training is the foundation every product and post-training effort builds on, and the team concentrates on a handful of large training efforts rather than spreading thin. The Opportunity You'll run controlled experiments on large models and let the data settle the arguments. You'll have the compute to test real hypotheses at scale, plus room to lead your own projects alongside the flagship runs. What You'll Do Research model architecture, training algorithms, optimisers and data pipelines Lead small projects independently while contributing to flagship training runs Design scaling-law experiments that set data, architecture and hyperparameter choices Scale training across thousands of accelerators with sound fault tolerance Build the dev tooling that keeps the research team moving quickly Work across the stack, from kernel throughput to high-level model design Design for downstream serving cost as well as model quality What You'll Bring Essential MS or PhD in CS, ML or a related field PyTorch distributed training, including FSDP and Megatron-style tensor or pipeline parallelism Debugging loss spikes, divergence and throughput regressions at scale Building and balancing data mixtures and tokenization pipelines Desirable Publications at NeurIPS, ICML, ICLR or similar venues FP8 or other low-precision training Custom CUDA or Triton kernels, or SSM-style and other non-standard architectures We encourage you to apply even if you don't meet every requirement. The right mindset matters as much as the right CV.   Apply Now If you want your experiments to shape the models themselves, we'd like to hear from you. Send your CV and we'll share the full brief in a confidential conversation.
Sam WarwickSam Warwick
United States
Senior Engineer, ML
Senior Engineer Remote (US) | Permanent | Base salary plus bonus and equity eligibility DeepRec has partnered with an autonomous vehicle company to hire a Senior Engineer for its ML data services team. You'll build the services and pipelines that turn terabytes of raw data into the datasets autonomy ML teams train and test on. THE OPPORTUNITY Every model the autonomy teams ship depends on what your systems deliver. You'll own the backend that stores and serves it, and help shape how the team plans and builds. WHAT YOU'LL DO • Design and build RESTful APIs and microservices for labelling and annotation workflows • Build and run scalable cloud ETL pipelines delivering training and simulation datasets • Own critical, highly available backend services handling terabytes of data • Set objectives, timelines and deliverables with engineering leadership and stakeholders • Design monitoring and observability for the MLOps pipelines • Mentor junior engineers through pairing sessions on code quality and SDLC practice WHAT YOU'LL BRING Essential • Significant Python backend experience building REST APIs and microservices • Production AWS experience, such as DynamoDB, EKS, Lambda or S3 • Pipeline orchestration with Step Functions, Airflow or Prefect • Experience mentoring engineers and planning roadmaps with cross-functional teams Desirable • Large-scale processing with Ray, Beam or Spark • Vector databases for embedding retrieval • Autonomous driving industry experience We encourage you to apply even if you don't meet every requirement. The right mindset matters as much as the right CV. WHAT'S IN IT FOR YOU • Base salary plus bonus and equity eligibility • Fully remote within the US • Medical, dental and vision cover, plus health savings account options • 401(k) with company match, life insurance and pet insurance • Ownership of critical services the autonomy ML teams rely on APPLY NOW If building the data foundations behind self-driving systems sounds like your kind of problem, we'd love to hear from you. Apply now and start the conversation.
Sam WarwickSam Warwick
United States
Principal Engineer, Simulation Infrastructure
Principal Engineer Team Lead Hybrid, US (occasional on-site time at company offices) | Permanent | Up to 10% travel DeepRec has partnered with an autonomous vehicle company to hire a Principal Engineer Team Lead for its simulation infrastructure team. You'll lead the engineers behind cloud infrastructure that handles millions of simulation runs a month and feeds directly into release gating. THE OPPORTUNITY Your infrastructure sets how fast autonomy engineers can test changes and how confidently the company ships. You'll own the technical roadmap and the team that delivers it. WHAT YOU'LL DO • Lead, mentor and grow a multi-site team of infrastructure engineers • Set the multi-year technical roadmap for the team • Architect high-throughput, multi-cluster orchestration for millions of monthly simulation runs • Cut AWS spend through EC2 sizing and spot queues with automated failover • Build plug-and-play engine abstractions and System Under Test tooling • Own cost, throughput and queue observability, with real-time dashboards • Lead postmortems and root-cause analysis to improve test stability WHAT YOU'LL BRING Essential • Significant experience in autonomous vehicles, robotics or large-scale cloud infrastructure • Proven track record leading engineering teams and setting technical roadmaps • Production Python and C++ in Linux environments • Deep AWS scaling experience, including EC2, spot instances and cost management Desirable • Autonomous driving simulation, such as log sim, closed loop or scenario formats • GitLab CI/CD, Docker and Airflow orchestration • HIL bench integration, CAN protocols or camera and LiDAR sensor simulation We encourage you to apply even if you don't meet every requirement. The right mindset matters as much as the right CV. WHAT'S IN IT FOR YOU • Principal-level ownership of a multi-year technical roadmap • A team at the centre of how autonomy software gets released • Scale problems few teams face, with millions of runs each month • Hybrid working with occasional on-site collaboration • Medical, dental and vision cover, plus 401(k) with company match APPLY NOW If leading the infrastructure that decides how autonomy software ships sounds like your next step, we'd love to hear from you. Apply now and start the conversation.
Sam WarwickSam Warwick